

At INMA Berlin, publishers sketch a new framework for AI compensation
World Congress Blog | 13 May 2026
While AI workflow transformation dominated many conversations at the INMA World Congress of News Media last week, a smaller but increasingly consequential discussion focused on how publishers may eventually be compensated when AI systems use journalism.
Across study tours, conference sessions, and seminars, executives from Sky News, BBC, Axel Springer, IAB Tech Lab, and Deutsche Presse-Agentur (DPA) described a shift from defensive responses to scraping and search disruption toward licensing agreements, usage tracking, technical standards, publisher controls, and agentic transaction systems that could eventually automate compensation between AI systems and news companies.
At the centre of many discussions was the growing concern that AI systems are consuming journalism without consistently providing attribution, audience referrals, or payment.
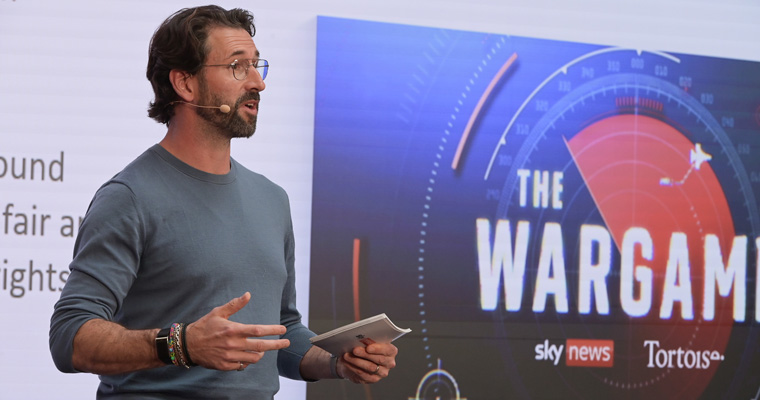
Andy Thomson, executive director of business operations at Sky News Group, described AI-generated answers as increasingly replacing original reporting while publisher content is “often imported without permission, attribution, or payment.”
That pressure has intensified as publishers report declining search traffic and growing fears that AI-generated summaries may reduce direct audience relationships.
During one study tour discussion, participants referenced concerns about steep traffic declines to recipe and utility journalism as AI systems increasingly answer practical queries directly.
AI increases the value of trusted journalism
Despite concerns over traffic erosion and compensation, many executives also said AI could increase the strategic importance of trusted journalism brands.
BBC executives said internal research conducted with the European Broadcasting Union found that 45% of AI-generated news outputs contained “significant errors,“ heightening concerns around sourcing and accuracy.
Several executives suggested that dynamic may ultimately strengthen demand for verified journalism inside AI systems themselves.
At DPA, executives described how the German news agency is expanding AI products, fact-checking operations, and newsroom initiatives while maintaining a strong emphasis on independent verification.
Others framed the industry’s challenge as shifting from content abundance to trust differentiation.
Claudius Senst, chief operating officer at Axel Springer, framed the question more fundamentally during a conference session focused on AI-first publishing models.
“What happens to journalism and to the definition of this, when scarcity of content is gone?” Senst asked.
That question echoed throughout the week.
As AI systems make content generation increasingly cheap and abundant, publishers increasingly appear to be repositioning journalism not merely as content, but as authenticated, rights-managed, trusted intellectual property.
SPUR emerges as a publisher response
One of the week’s most concrete developments around AI remuneration came from Thomson’s discussion of SPUR — Standards of Publisher Usage Rights — a coalition founded earlier this year by Sky News, BBC, The Guardian, The Telegraph, and the Financial Times.
Thomson said the initiative aims to establish “ground rules” allowing publishers to track how content is used by AI systems and ensure they are “properly and proportionately paid for it.”
“This isn’t about limiting competition or coordinating commercial behaviour,” Thomson said. “It’s about transparency, fairness and accountability.”
Executives repeatedly framed collaboration as essential because individual publishers lack leverage against global AI platforms acting at internet scale.
At the BBC seminar, executives similarly described SPUR as an attempt to create “shared standards and licensing frameworks” so AI developers could access trusted journalism “responsibly” while publishers retained “control and fair value.” Another executive urged not to create new standards but rather collaborate and build on successful standards that have been peer reviewed such as the Content Monetisation standard and others by IAB.
It’s a really important point. IAB has done a bunch of good work already, SPUR is just starting so the industry needs to be careful not to overindex on SPUR and give credit where it is due.
Executives increasingly framed collective standards as more scalable than relying solely on lawsuits or one-off licensing deals.
A parallel licensing standard gains momentum
An executive briefing on news tech platforms surfaced a second, complementary initiative gaining traction across the industry: Really Simple Licensing (RSL), an associated nonprofit collective designed to manage blanket licences on publishers’ behalf.
The briefing reported that more than 1,500 publishers, media companies, and brands have engaged with the RSL framework, and that major content delivery networks — including Cloudflare, Akamai, and Fastly — are collaborating on enforcement infrastructure. CDN involvement matters because it gives the standard a path to actual enforcement at the network layer, rather than relying solely on publisher-side blocking.
RSL has built a system that delivers open and interoperable rights signalling, paired with a collective that could offer AI firms one-to-many access while providing publishers with sustainable royalty distributions.
Together, IAB, SPUR, and RSL suggest the industry is moving toward standardised, machine-readable licensing rather than a patchwork of bilateral deals.
Open standards and machine-readable licensing
The strongest technical presentation on this shift came during the advertising seminar from Shailley Singh, EVP product and COO of IAB Tech Lab.
Singh said publishers need infrastructure that allows AI systems to interact with journalism through structured permissions and licensing frameworks rather than uncontrolled scraping.
“We are trying to just put the communication protocols together,” Singh said.
IAB Tech Lab recently released what Singh called the “Content Monetisation Protocol version one,” an API framework designed to manage AI access to publisher content.
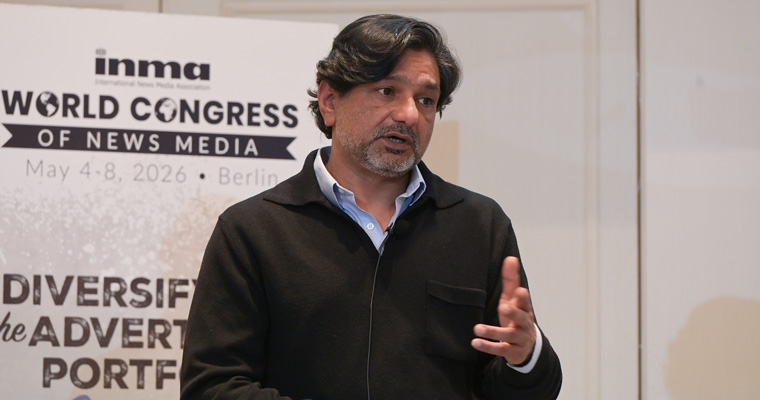
The goal, he said, is not simply blocking AI crawlers but enabling publishers to track AI usage, apply licensing terms programmatically, and redirect unauthorised bots toward licensing agreements. Both SPUR and RSL have given feedback and will ensure that this is compatible with standards and tools they are building.
Several companies — including Microsoft and Amazon — are already developing marketplaces intended to facilitate compensation arrangements between AI systems and publishers.
The larger implication discussed throughout the week was that publisher remuneration may increasingly move from negotiated contracts toward scalable, machine-readable usage frameworks and automated transactions.
Archives gain new value
A less-discussed but commercially significant theme from the briefing concerned the renewed value of news archives.
Because AI models periodically retrain and rely on retrieval-augmented generation (RAG) systems that pull from large content stores, backfiles regain economic value with each model update. Archives, in this framing, are not a sunk historical cost but a renewable licensable asset.
The discussion found that publishers with deep, rights-cleared, well-structured archives may be better positioned to capture recurring licensing revenue than those focused solely on current output — particularly as licensees increasingly pay for premium, specialist, and recent content at differentiated rates.
The regulatory backdrop
Several discussions across the week placed the AI compensation conversation against a shifting legal and regulatory landscape that publishers increasingly believe is moving in their favour.
The briefing noted the United States has not granted an AI training carve-out under copyright law, the European Union’s Digital Services Act and Digital Markets Act remain active and aligned with publisher interests, Germany has moved in a similar direction, and Australia is strengthening copyright protections around AI.
Competition and consumer authorities — including the European Commission and the UK’s Competition and Markets Authority — are also actively shaping how AI platforms separate search-related crawling from AI training crawling, and pushing toward licensing-first approaches.
Executives made the point that this regulatory alignment may create a narrow window for publishers to establish standards before AI consumption patterns harden into industry defaults.
Publishers need to prepare data and infrastructure
Beyond licensing itself, many executives said publishers must regain technical control over their own data and monetisation infrastructure.
To license content, publishers need to be able to deliver rights cleared materials, usually via an API, in a structured way. Many are not yet set up for that and one executive suggested that the cost and effort of setting this up was substantial.
Practical guardrails publishers are demanding
The briefing also surfaced an emerging consensus around what publishers should require in AI licensing contracts, even as broader standards develop.
Publishers need to consider bot-class separation — distinguishing search-related crawling from AI training and inference crawling — alongside telemetry requirements giving publishers visibility into how their content is used, audit rights, and what one participant called a “big red button“: a kill switch if the terms are not met or there was damage to the oiblishers brand or traffic.
The briefing emphasised that technical enforcement is essential to drive paid licensing.
The takeaways
The conversations in Berlin suggested the industry is moving toward a far more structured and technical approach to AI compensation than many executives anticipated even a year ago.
Instead of focusing solely on lawsuits or broad platform negotiations, publishers are now building:
-
Shared licensing standards (IAB, SPUR, RSL).
-
Machine-readable permissions systems (IAB, RSL).
-
Usage-tracking protocols and CDN-based enforcement.
-
Agentic transaction infrastructure.
-
Collective bargaining frameworks aligned with active regulatory pressure.
-
Archive monetisation strategies tied to model retraining cycles.
The result may become a new remuneration architecture for journalism — one where payments, permissions, attribution, and discovery are increasingly embedded directly into the infrastructure of AI systems themselves.
For publishers, the challenge now is whether they can build those standards quickly enough to retain leverage before AI-native consumption models become dominant.
All photos by Robert Downs Photography.
Related Articles
-

Marketers should outsource tasks, not thinking
25 October 2026 -

WSJ executive councils show how publishers build communities th...
19 October 2026 -

AI’s effect on super user math
15 September 2026 -

What I told 40 CEOs (and won’t gatekeep from you)
30 August 2026 -

At Mediacorp’s CNA, loyalty means giving audiences a reason to ...
20 August 2026 -

Tribun Network turns print “dots” into AI-powered insight
20 August 2026 -

Nation Media Group focuses editorial strategy on stories that m...
4 August 2026 -

Briefly News empowers journalists with AI tool suite Nova
4 August 2026
Upcoming Events
-

Subscriber Acquisition Master Class
10-17 November 2026
-

Media Advertising Summit
New York, United States
07-10 December 2026
-

AI-Native News Product Master Class
18-25 February 2027
-

Media Subscriptions Summit
Oslo, Norway
08-12 March 2027
-

World Congress of News Media
New York, United States
25-30 April 2027
-

Branded Content & Partnerships Master Class
20-27 May 2027
-

Subscriber Retention Master Class
17-24 June 2027
-

Conferencia Latinoamericana
15-16 July 2027
-

South Asia News Media Festival
New Delhi, India
19-22 July 2027
-

Asia/Pacific News Media Summit
19-20 August 2027
-

CEO Roundtable at Kilkenny
Kilkenny, Ireland
24-26 August 2027
-

Media Innovation Week
Amsterdam, The Netherlands
27 September - 01 October 2027








